Piracy

French Court Orders Search Engines, ISPs To Block Pirate Sites 75

rtoz sends word that a French court has ordered Google, Yahoo, and Microsoft to remove 16 unauthorized video streaming sites from their search results. Many ISPs were also ordered to block access to the sites. According to TorrentFreak, "The court ruled that the film industry had clearly demonstrated that the sites in question are 'dedicated or virtually dedicated to the distribution of audiovisual works without the consent of their creators,' thus violating their copyrights. As a result the search services of Google, Microsoft, Yahoo and local company Orange are now under orders to 'take all necessary measures to prevent the occurrence on their services of any results referring to any of the pages' on these sites. Several ISPs – Orange, Free, Bouygues Télécom, SFR, Numéricable and Darty Télécom were also ordered to 'implement all appropriate means including blocking' to prevent access to the infringing sites."
Government

FOIA: NSA Contracts Stored In Paper Files, Unsearchable, Unindexed 114

v3rgEz writes "Wish you were a little more organized? Have trouble finding that archived contract when you actually need it? Don't feel too bad: The National Security Agency has the same problem, claiming that its contract database is stored manually and impossible to search by topic, category, or even by vendor in most cases."
Music

Real-Time Radio Search Engine From Music Industry's Nemesis 59

An anonymous reader writes "From the guy who brought you CD syncing and the original music locker (both of which saw lawsuits from record labels) comes the latest invention to rock the music world: a real-time radio search engine. 1000s of worldwide stations are indexed in real-time and users can search and play most any popular artist — even the digital holdouts (Tool, Led Zeppelin, etc) that are unavailable on paid services like Spotify. (Kinda wonder why Google hasn't done this.) Link on main page points to an API for those who want to build mobile and web services."
Privacy

P2P Data Not Private, But It Could Be 59

Frequent correspondent Bennett Haselton writes with a forward-looking response to a recent ruling that peer-to-peer network participants have little privacy interest in files stored on their computer and that they have made available via P2P. Writes Bennett: "A court rules that law enforcement did not improperly 'search' defendants' computers by downloading files that the computers were sharing via P2P software. This seems like a reasonable ruling, but such cases may become rare if P2P software evolves to the point where all downloads are routed anonymously through other users' computers." Read on for the rest.
Privacy

Credit Card Numbers Still Google-able 157

Slashdot contributor Bennett Haselton writes "In 2007, I wrote that you could find troves of credit card numbers on Google, most of them still active, using the simple trick of Googling the first 8 digits of your credit card number. The trick itself had been publicized by other writers at least as far back as 2004, but in 2013, it appears to still be just as easy. One possible solution that I didn't consider last time, would be for Google itself to notify the webmasters and credit card companies of the leaked information, and then display a warning alongside the search results." Read on for the rest of Bennett's thoughts.
Censorship

French Court Orders Google To Block Pictures of Ex-F1 Chief Mosley 180

Virtucon writes "This one goes to the old adage 'closing the stable door after the horse bolted.' A French court on Wednesday ruled that Google must remove from its search results photos of a former Formula One racing chief, Max Mosley, participating in an Nazi-themed orgy. Google could be fined up to 1,000 Euros/day for not complying. What's strange here is that Mosley A) Sued in a French Court B) Didn't go after anybody else other than Google and C) has definitely strange tastes in extracurricular activities. In this day and age it's laughable to think that once your private photos/videos hit the Internet that you have any expectation of reining them in or filtering the embarrassing parts out. Google isn't the only game in town so to speak in terms of Internet search. I wonder if his lawyers checked out Yahoo or WebCrawler?"
Google

Google Bots Doing SQL Injection Attacks 156

ccguy writes "It seems that while Google could really care less about your site and has no real interest in hacking you, their automated bots can be used to do the heavy lifting for an attacker. In this scenario, the bot was crawling Site A. Site A had a number of links embedded that had the SQLi requests to the target site, Site B. Google Bot then went about its business crawling pages and following links like a good boy, and in the process followed the links on Site A to Site B, and began to inadvertently attack Site B."
Google

Google Relying On People Power For 'Helpouts' 57

Nerval's Lobster writes "While Google built its highly profitable search business atop a complex mix of algorithms and machine learning, its latest initiative actually depends on people power: Helpouts, which allows users (for a fee) to video-chat with experts in particular fields. Google has rolled out the service with a few brands in place, such as One Medical and Weight Watchers, and promises that it will expand its portfolio of helpful brands and individuals over the next several months. Existing categories include Cooking, Art & Music, Computers & Electronics, Education & Careers, Fashion & Beauty, Fitness & Nutrition, Health, and Home & Garden. Some Helpouts charge nothing for their time; for example, the 'Cooking' section of the Website already features a handful of chefs willing to talk users through baking, broiling, slicing and dicing for free. A few vendors in the Computers & Electronics section, by contrast, charge $2 per minute or even $200 per Hangout session for advice on WordPress setup, Website design, and more. So why is Google doing this? There are plenty of Websites that already dispense advice, although most rely on the written word—Quora, for example, lets its users pose text-based questions and receive answers. There's also rising interest in Massive Open Online Courses, also known as MOOCs, in which thousands of people can sign online to learn about something new. In theory, Helpouts (if it's built out enough) could make Google a player in those markets, as well as specialized verticals such as language learning — and earn some healthy revenue in the process."
Google

You're Only As Hirable As Your Google+ Circles 195

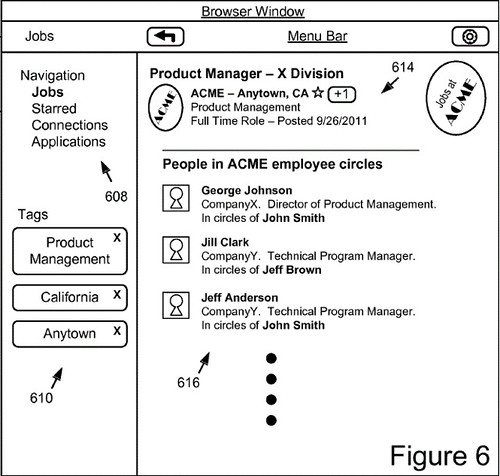
theodp writes "A pending Google patent for Identifying Prospective Employee Candidates via Employee Connections lays out plans for data mining employees' social graphs to find top job candidates. According to the patent application, the system would consider factors including the performance of the employees at the company whose circles you are in — under the assumption that the friends of top performers are more likely to be top performers themselves. It's the invention of three Googlers, including an HR VP who was quoted recently in an article that questioned the wisdom of certain Google hiring practices said to encourage 'echo chamber' hiring."
Advertising

Google Testing Banner Ads On Select Search Results 185

cagraham writes "Google promised in 2005 to never "ever" put banner ads on their search results, but that appears to be changing. The company confirmed to SearchEngineLand that it is running a "small experiment" involving large-scale banners on searches for Southwest Airlines, Virgin Atlantic, and Crate&Barrel, among others. The ads are being shown in less than 5% of searches, and only in the US, for now. Interestingly enough, the Google exec who wrote the no banner ads promise was Marissa Mayer, now CEO of Yahoo."
Microsoft

Some Bing Ads Redirecting To Malware 146

An anonymous reader writes "Security firm ThreatTrack Security Labs today spotted that certain Bing ads are linking to sites that infect users with malware. Those who click are redirected to a dynamic DNS service subdomain which in turns serves the Sirefef malware from 109(dot)236(dot)81(dot)176. ThreatTrack notes that the scammers could of course be targeting other keywords aside from YouTube. The more popular the keywords, the bigger the potential for infection."
Crime

Google Cracks Down On Mugshot Blackmail Sites 251

Google is apparently displeased with sites designed to extract money from arrestees in exchange for removing their mugshot pictures online, and is tweaking its algorithms to at least reduce their revenue stream. From the article at The New York Times: "It was only a matter of time before the Internet started to monetize humiliation. ... The sites are perfectly legal, and they get financial oxygen the same way as other online businesses — through credit card companies and PayPal. Some states, though, are looking for ways to curb them. The governor of Oregon signed a bill this summer that gives such sites 30 days to take down the image, free of charge, of anyone who can prove that he or she was exonerated or whose record has been expunged. Georgia passed a similar law in May. Utah prohibits county sheriffs from giving out booking photographs to a site that will charge to delete them. ... But as legislators draft laws, they are finding plenty of resistance, much of it from journalists who assert that public records should be just that: public."
Government

Taking Back Control of Your Data, With Fine Grained, Explicit Permissions 55

BrokenHalo writes with a story at New Scientist outlining one approach to reclaiming your online privacy: a software gatekeeper (described in detail in a paper from last year) from two MIT developers. "Developers Sandy Pentland and Yves-Alexandre de Montjoye claim OpenPDS (PDF) disrupts what NSA whistleblower Edward Snowden called the 'architecture of oppression,' by letting users see and control any third-party requests for their information – whether that's from the NSA or Google. Among other things, the Personal Data Store includes a mechanism for fine-grained management of permissions for sharing of data. Personally, I'm not convinced that what the NSA demands outright to be shared is as relevant as what they surreptitiously take without asking."
Google

Google To Encrypt All Keyword Searches 224

Hugh Pickens DOT Com writes "Danny Sullivan reports that in the past month, Google has quietly made a change aimed at encrypting all search activity to provide 'extra protection' for searchers, and possibly to block NSA spying activity. In October 2011, Google began encrypting searches for anyone who was logged into Google. The reason given was privacy. Now, Google has flipped on encryption for people who aren't even signed-in. In June, Google was accused of cooperating with the NSA to give the agency instant and direct access to its search data through the PRISM spying program, something the company has strongly denied. 'I suspect the increased encryption is related to Google's NSA-pushback,' writes Sullivan. 'It may also help ease pressure Google's feeling from tiny players like Duck Duck Go making a "secure search" growth pitch to the media.'"
The Internet

Jonathon Fletcher: The Forgotten Father of the Search Engine 95

PuceBaboon writes "If you were under the impression that Brin and Page invented the search engine while working out of a garage somewhere in Silicon Valley then think again. The first practical web-crawler with a searchable index, JumpStation, was running out of Stirling University, Scotland, twenty years ago this year, long before Google came into existence. In a tale all too typical of the U.K. tech industry through the years, JumpStation's creator, Jonathon Fletcher, was unable to find funding for his brainchild and commercial exploitation of the idea fell to others. Jonathon, who was a panel member at the ACM SIGIR conference in Dublin earlier this year is now quite serene about the missed opportunity, despite his frustration at the time. Meanwhile, Stirling University is quoted as 'now looking at a way to mark' Jonathon's achievement."
China

Yahoo Pulls Out of China 79

judgecorp writes "Yahoo has closed its news and community services in China, having already closed its email services there. A farewell message on Yahoo's Chinese site doesn't say much, but it seems Yahoo is ceding the territory to Chinese firm Alibaba, in whom it has a stake."
The Internet

Dotless Domain Names Prohibited, ICANN Tells Google 132

New submitter gwstuff writes "Last year, Google filed applications for about 100 top level domains. These included .app, .cloud and .lol, but perhaps most prominently .search, which they had requested to operate as a 'dotless' domain. [Friday], ICANN gave their verdict on the idea that would make this URL valid : NO. Here is the formal announcement, and a related Slashdot story from last year. So that's that. But it may still be granted the rights for the remaining 100. Is prime dot-com real estate going to become a thing of the past?"
AI

Why Computers Still Don't Understand People 277

Gary Marcus writes in the New Yorker about the state of artificial intelligence, and how we take it for granted that AI involves a very particular, very narrow definition of intelligence. A computer's ability to answer questions is still largely dependent on whether the computer has seen that question before. Quoting: "Siri and Google’s voice searches may be able to understand canned sentences like 'What movies are showing near me at seven o’clock?,' but what about questions—'Can an alligator run the hundred-metre hurdles?'—that nobody has heard before? Any ordinary adult can figure that one out. (No. Alligators can’t hurdle.) But if you type the question into Google, you get information about Florida Gators track and field. Other search engines, like Wolfram Alpha, can’t answer the question, either. Watson, the computer system that won “Jeopardy!,” likely wouldn’t do much better. In a terrific paper just presented at the premier international conference on artificial intelligence (PDF), Levesque, a University of Toronto computer scientist who studies these questions, has taken just about everyone in the field of A.I. to task. ...Levesque argues that the Turing test is almost meaningless, because it is far too easy to game. ... To try and get the field back on track, Levesque is encouraging artificial-intelligence researchers to consider a different test that is much harder to game ..."
United States

Federal Judge Rules NYC "Stop and Frisk" Violated Rights 308

In a mixed ruling for Fourth Amendment rights, a federal judge today ruled that NYC's Stop-and-Frisk program violated constitutional rights due to disproportionately targeting minorities. However, despite the program being unconstitutional in its current form, it will not stop. From the New York Times: " Judge Scheindlin also ordered a number of other remedies, including a pilot program in which officers in at least five precincts across the city will wear body-worn cameras in an effort to record street encounters. She also ordered a 'joint remedial process' — in essence, a series of community meetings — to solicit public input on how to reform stop-and-frisk. ... The Supreme Court had long ago ruled that stop-and-frisks were constitutionally permissible under certain conditions, and Judge Scheindlin stressed that she was 'not ordering an end to the practice.' But she said that changes were needed to ensure that the street stops were carried out in a manner that “protects the rights and liberties of all New Yorkers, while still providing much needed police protection.' ... The judge found that the New York police were too quick to deem as suspicious behavior that was perfectly innocent, in effect watering down the legal standard required for a stop. " The ruling itself (PDF). Bloomberg is furious about the decision, and the city, naturally, intends to appeal.
AI

Is 'Fair Use' Unfair To Humans? 259

An anonymous reader writes "This article in Wired advances the idea that humans are losing the copyright battle against machines because the fair use laws are tilted against them. The writer wanted to include photos in his book, but the licensing fees were too high. The aggregators, though, like Google, are building their own content by scraping all of the photos they can find. If anyone complains, they just say, 'Fill out a DMCA form.' Can humans compete against the machines? Should humans be able to use the DMCA to avoid copyright fees too? Should web sites be able to shrug and say, 'Hey, we just scraped it?'"

Slashdot Top Deals